LakeAgent
Deep Research over Data Lakes
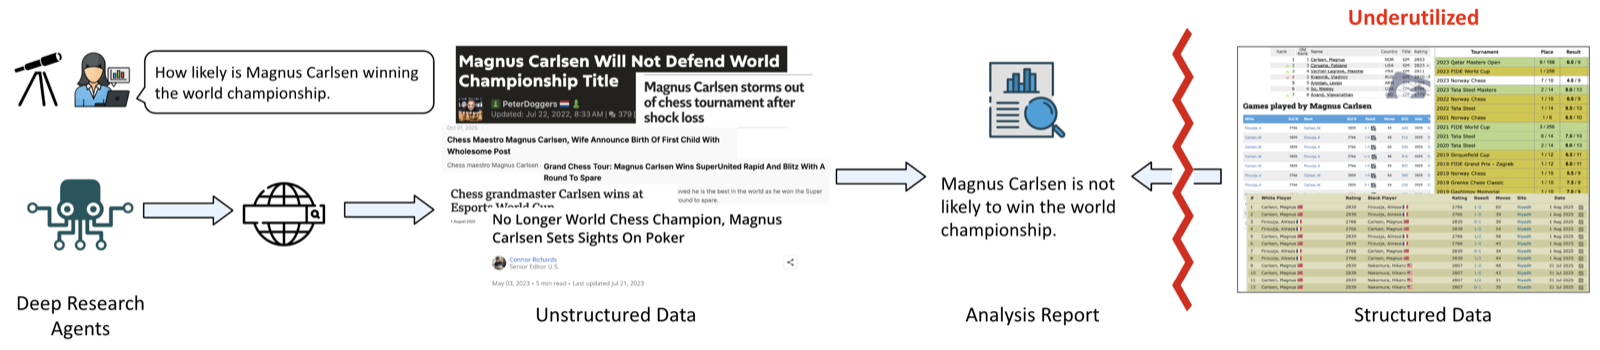
One of the most exciting LLM applications has been deep research agents that search web and unstructured information to synthesize answers. Unfortunately, current deep research agents ignore the abundant tabular datasets in public and enterprise data lakes, leaving them unable to answer analytic questions requiring enumeration, aggregation, or causal reasoning. We propose LakeAgent, a system that builds the missing infrastructure for deep-research agents to operate over terabytes of structured and unstructured data. Given a natural language question, the system automatically discovers relevant datasets, integrates heterogeneous sources, and produces verifiable answers with explicit provenance. For instance, estimating “How likely is Magnus Carlsen to win the next world championship cycle?” requires structured data (match histories, opponent pools) and unstructured data (participation intent, interviews).
Contributors
Haonan Wang*, Jiaxiang Liu*, Yurong Liu, Austin Senna Wijaya, Tianle Zhou, Eden Wu, Yijia Chen, Wanting You, Reya Vir, Daniela Pinto Veizaga, Grace Fan, Yusen Zhang, Juliana Freire, Eugene Wu
Publications
- SANA: What Matters for QA Agents over Massive Data Lakes? arXiv 2026
- LakeQA: An Exploratory QA Benchmark over a Million-Scale Data Lake ICML 2026
- Suna: Scalable Causal Confounder Discovery over Relational Data VLDB 2025
- DynoClass: A Dynamic Table-Class Detection System Without the Need for Predefined Ontologies TRL@NeurIPS 2024